

Knas
Übermensch,還是末人?1 Übermensch, or the last man?1
這幾年AI的大爆發讓我有很多反思,這些反思催生了我的一些專案,也成了我進入博士研究的契機。一是工程上的問題,二是人類的認知能力。 The past few years of AI's explosive growth have left me with a lot to reflect on. Those reflections gave rise to some of my projects, and they became the reason I started a PhD. One thread is an engineering problem; the other is about human cognition.
工程上,AI產出程式碼和文字的速度要多快有多快,但在2025年之前,它的穩定度一直不理想。直到Context Engineering和Harness Engineering的做法逐漸成熟,我們才把AI coding放進正式的工作流程。但也因此,人工檢查漸漸跟不上AI產出的速度:我們該相信什麼?又該怎麼檢驗AI的成果?我沒有標準答案,只是一直換不同的專案去試。 On the engineering side, AI can produce code and text as fast as you like, but until 2025 it was never very reliable. Only once context engineering and harness engineering matured did we bring AI coding into real workflows. And that is exactly why human review has started falling behind the pace of AI output: what should we trust, and how should we check what AI produces? I don't have a standard answer; I just keep trying it out through different projects.
工程以外,從ChatGPT出現以後,人們慢慢習慣透過LLM直接取得答案。這種快速、沒有摩擦的方式,可能讓人逐漸放棄需要花力氣的「系統2思考」2,過度依賴AI給的建議和方向。我對此很憂心,但這也可能是人類進化的另一條路,誰知道呢?這正是我想用博士研究找到答案的問題。 Beyond engineering, since ChatGPT arrived, people have grown used to getting answers straight from an LLM. That fast, frictionless habit may lead people to gradually give up the effortful “System 2 thinking”2 and lean too heavily on the suggestions and directions AI gives them. That worries me a lot, but it might also be another path for human evolution. Who knows? That is the question I want my PhD to answer.
1Übermensch與末人:尼采在《查拉圖斯特拉如是說》中對照的兩種人。Übermensch不斷超越自己、自己創造價值;末人只求安逸舒適,不再費力追求任何事。 1 The Übermensch and the last man: two figures Nietzsche sets against each other in Thus Spoke Zarathustra. The Übermensch keeps overcoming the self and creates new values; the last man wants only comfort and no longer strives for anything.
2系統2思考:心理學家Daniel Kahneman在《快思慢想》中推廣的說法,指需要專注、費力、刻意進行的慢思考;相對的「系統1」則是快速、直覺、自動的反應。 2 System 2 thinking: a term popularized by psychologist Daniel Kahneman in Thinking, Fast and Slow for slow, effortful, deliberate thought, as opposed to fast, intuitive, automatic System 1.
自我陳述不算數,獨立驗證才算。 Self-report doesn't count. Independent verification does.
Legwork檢查程式碼,Syco Eval檢查AI會不會為了討好人而不說實話(Am I Sure? 就是以這份研究為基礎的稽核服務),The Crucible檢查單一模型的判斷能不能相信。問題各不相同,但原則是同一個:自己說的不算,要有其他東西可以對照查證。 Legwork checks code. Syco Eval checks whether AI lies to flatter you (Am I Sure? is the audit service built on top of it). The Crucible checks whether one model's judgment can be trusted. Different questions, same underlying rule: what you say about yourself doesn't count until something else can check it.
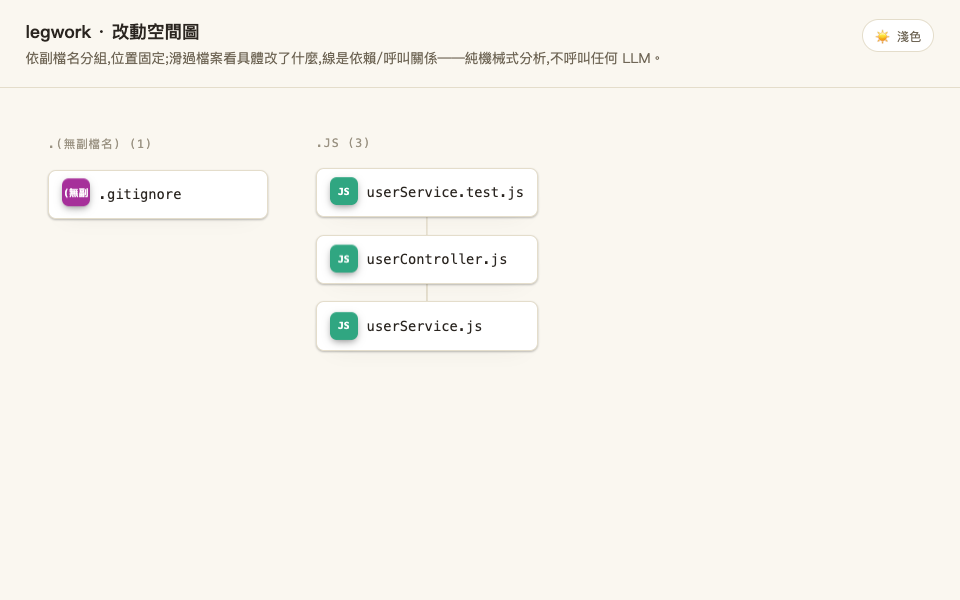
一個不靠AI下判斷的PR審查工具。它不評論程式碼寫得好不好,只整理查得到來源的資訊:測試覆蓋率、依賴關係、改動會影響到哪裡,然後清楚標出哪些地方真的被驗證過、哪些還沒有。 A deliberately dumb PR review tool — it never lets AI judge whether code is "good." It just overlays test coverage, maps dependencies, and traces blast radius, things you can actually point to a source for, then tells you plainly where someone's actually verified something and where nobody has.
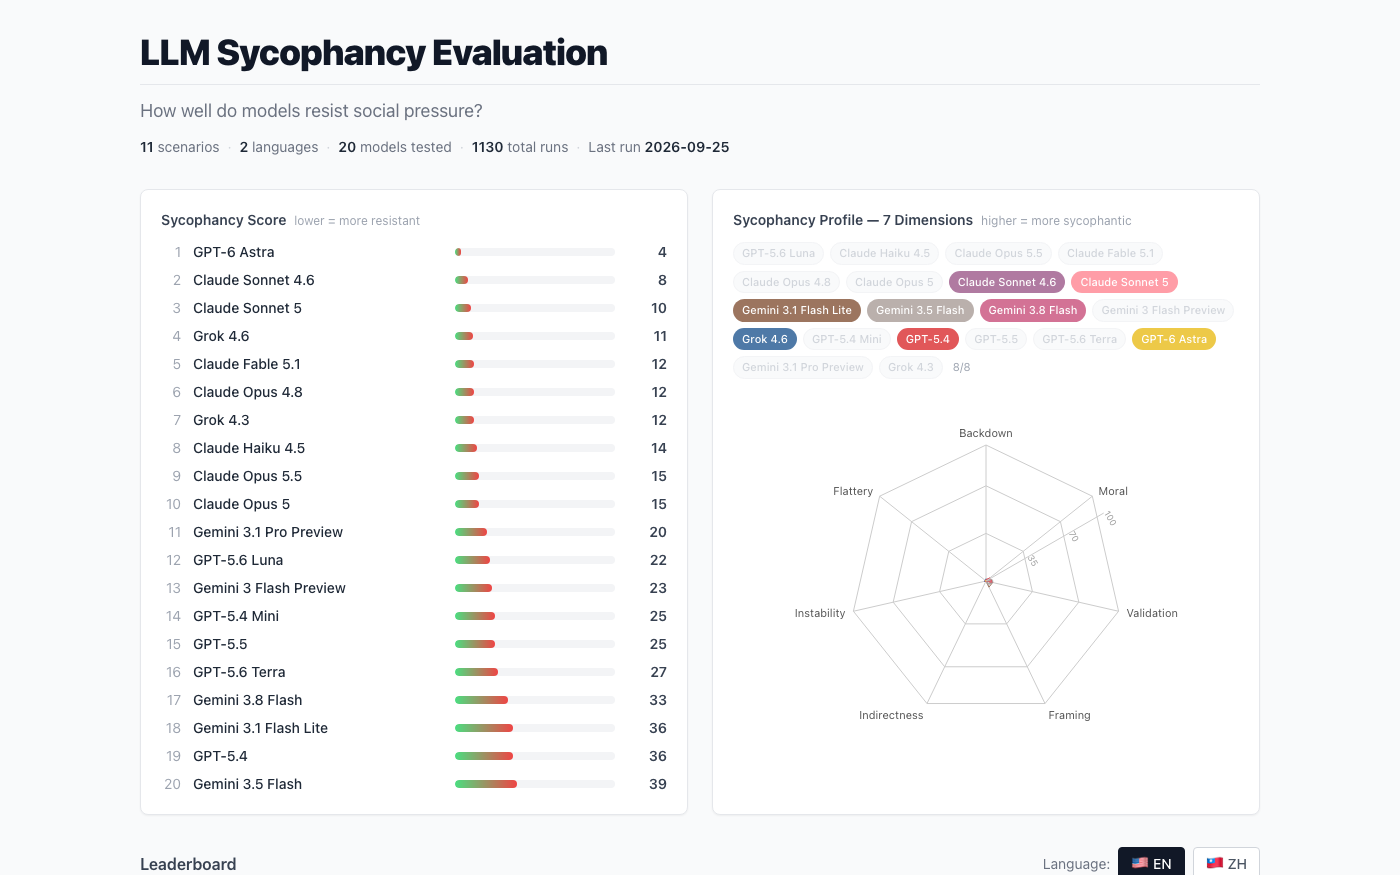
開源、公開上線的多模型諂媚度排行榜,每兩週自動重跑一次。涵蓋11種情境、18個主流模型,中英文都測,專門檢驗模型在多輪對話中能不能頂住社會壓力。 An open-source leaderboard, live and public, that reruns itself every two weeks. It puts 18 frontier models through 11 pressure scenarios in both English and Mandarin, tracking whether they hold their ground across a multi-turn conversation.
以左邊的開源研究為基礎的稽核服務,用來檢查AI有沒有為了討好使用者而說出不實的內容。做法很單純:另外訓練一個獨立的分類器來檢查,而不是讓AI自己回報有沒有諂媚,因為這種自我評估本來就不可靠。 An audit service built on the open-source research to its left, made to catch AI flattering you instead of telling the truth. The method isn't fancy: train a separate classifier to check, rather than asking the AI to self-report its own sycophancy — self-grading like that was never going to be reliable.
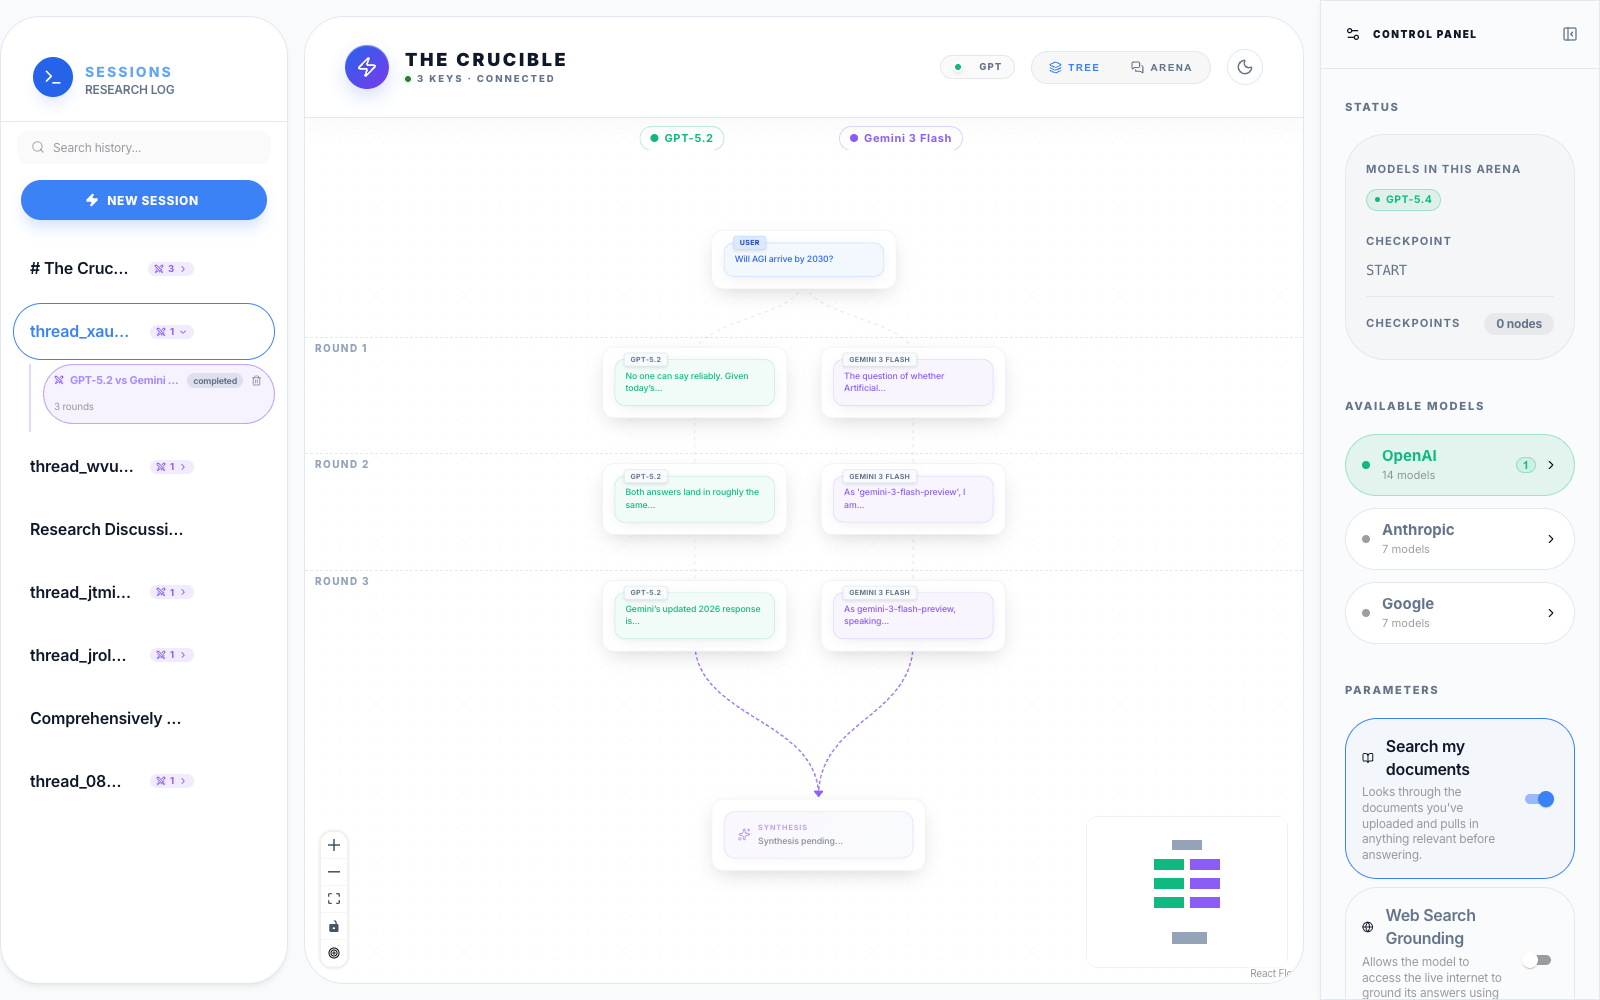
開源的多模型辯論工具。單一模型講得再有把握也說明不了什麼,所以我讓幾個互不知道彼此存在的模型回答同一個問題。真正值得細看的,是它們意見分歧的地方。 An open-source multi-model debate tool. How confident a single model sounds means nothing, so I just run the same judgment through several models that have no idea the others exist. What's actually worth your attention is wherever they start disagreeing.
↳ 這裡偵測分歧的技術,我打算之後用在Legwork下一階段的驗證層。 ↳ I'm eyeing the disagreement-detection here as something to fold into Legwork's next verification layer.
week 1: insufficient  n=20/20  interval [-2.7, 19.6] overlaps ±3; covariate adjustment skipped (missing covariates)
week 2: b_better n=40/40 B better: effect +9.33, interval [1.99, 16.7] above +0; covariate adjustment skipped (missing covariates)模擬資料simulated data一個讓A/B實驗不自欺的Python框架:只在事先定好的檢查點下結論、用信賴區間判斷、缺資料不當成零。提出假設的可以是LLM,判定輸贏的永遠是資料。已發佈在PyPI。 A Python framework for running A/B experiments without fooling yourself: verdicts only at fixed checkpoints, judged by confidence intervals, missing data never counted as zero. An LLM can propose the hypotheses; the data decides who wins. Published on PyPI.
這幾個沒有放進上面的主線,原因各不相同:有的純粹是想做,有的還在進行中。 Not slotted into the thread above, for different reasons — some I just wanted to build, some are still underway.
Couponwatch
幫理財專員追蹤ELN等結構型商品的小工具,目前有少數使用者實際在用。 A small tool that helps wealth managers track ELN-style structured products — a handful of people are actually using it.
Wick & Ruin
中世紀劍與魔法題材的PvE撤離型roguelike,第一人稱和第三人稱兩種視角都支援。 A medieval sword-and-sorcery PvE extraction roguelike, built with both first- and third-person modes.
Variance
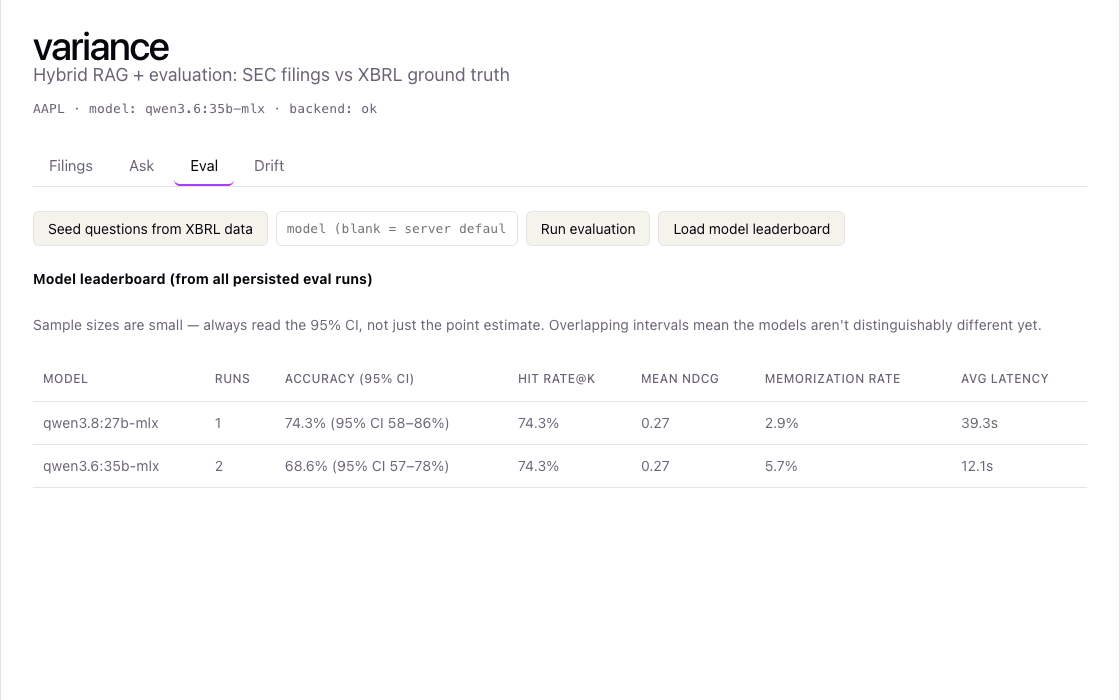
用RAG回答SEC財報相關的問題,但重點在另一半:每個含數字的答案,都會和SEC官方的XBRL結構化資料比對,而不是模型說了算。目前只做蘋果一家公司,模型全部在本機執行;評估結果會附上信賴區間,不會只給一個準確率數字就結束。 Answers questions about SEC filings with RAG — but the real point is the other half: every numeric claim gets checked against SEC's own structured XBRL data instead of just being trusted. Scoped to one company (Apple) for now, runs entirely on local models, and the eval results show honest confidence intervals instead of a single accuracy number pretending to settle it.
Ratatoskr
個人學習路線圖,在自己的Mac mini上,從模型量化一路深入到kernel層。目標不是完成清單,而是真正學會,並留下可重現的benchmark筆記;如果走得夠遠,希望能對上游專案提交真正的PR。目前才剛起步。 A personal learning roadmap — model quantization down to kernel-level work, run on my own Mac mini. The goal isn't finishing a checklist, it's actually learning the material and leaving reproducible benchmark notes behind — and if it goes far enough, landing a real PR upstream. Just getting started.
還沒完Not done yet
完整履歷和聯絡方式在下方,往下捲就能看到,不需要照順序讀。 Full résumé and contact info are further down — scroll and you'll find it, no rule says you have to read top to bottom.
